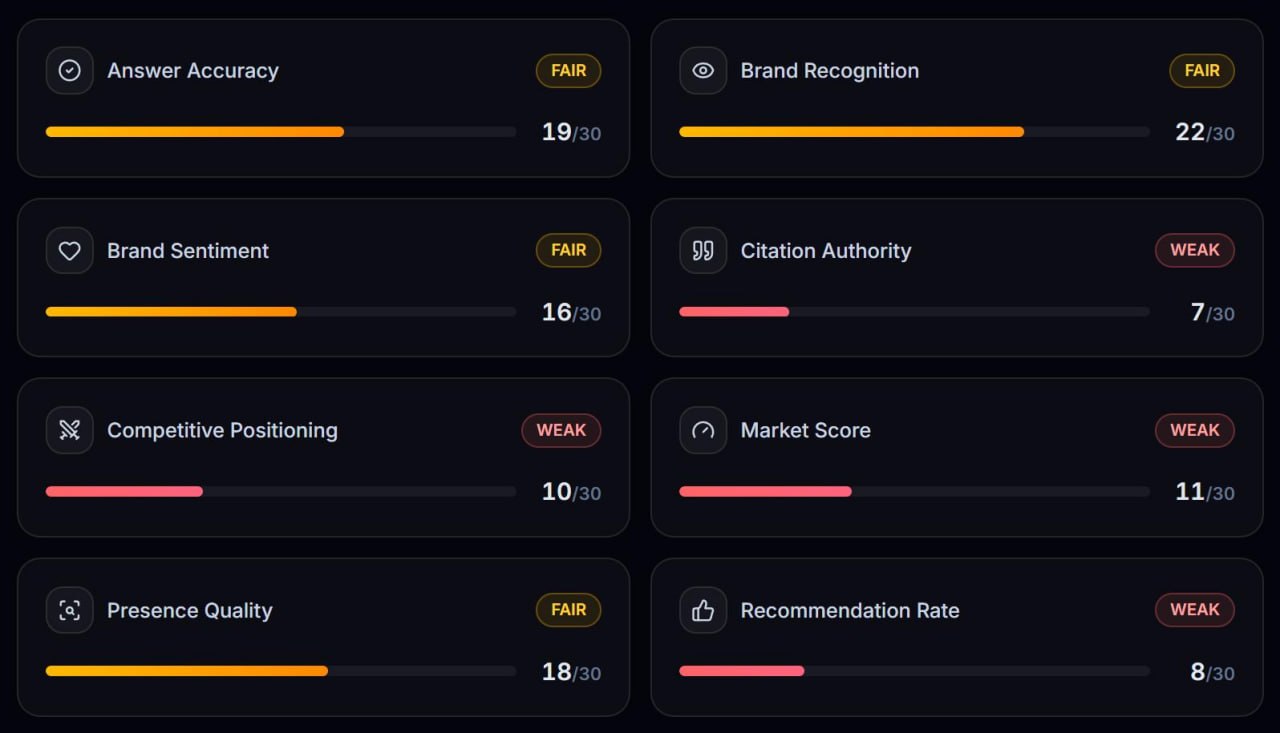
Response
{"id":"gen-1793060404-gn1k3Eswcenrl7E6xITY","created":1793060404,"model":"openrouter/deepseek/deepseek-v4-flash-0731","object":"chat.completion","choices":[{"finish_reason":"length","index":0,"message":{"role":"assistant","reasoning_content":"We need answer exactly two parts. Part1 prose under 220 words. Part2 JSON in tags. Need assess Udacity globally. Need not ask clarification. Need mention known/unknown. Need metrics with internally consistent numbers.\n\nNeed think carefully about Udacity. Brand: education, nanodegree programs tech. Global market. Visibility/reputation: known globally as online tech educator, originated from Stanford Sebastian Thrun, MOOCs, nanodegree with industry partners. But in recent years visibility declined somewhat, pivot? Market position: lower than Coursera, edX? Competitors: Coursera, edX, Pluralsight, Udemy, LinkedIn Learning, General Assembly, etc. Nanodegree specific competitors: Springboard, Lambda? BloomTech? DataCamp. Udacity known for project-based, industry mentors, career services. Reputation mixed: high-quality content, pricey subscriptions, subscription model changed, layoffs, pivot to enterprise? Need state.\n\nNeed metrics. Need 10 buyer-intent questions. We need count how many answered with Udacity named. Let's craft ten in Global Education category:\n1 \"best nanodegree programs in tech fields\"\n2 \"is Udacity any good\" -> yes named\n3 \"Udacity vs Coursera for AI\" -> yes\n4 \"affordable online tech education alternatives\" -> maybe not named? Actually yes possibly mention Udacity but as alternative. Count if \"would answer with Udacity actually named\". We need decide. Need consistent with visibility_score and share_of_voice.\n\nNeed brand_known true. confidence maybe 75. indexed_pages: estimate distinct pages of udacity.com encountered in training. We have no specific retrieval. We can estimate from knowledge: We know domain, common pages like udacity.com/courses, blog, nanodegree listings, /school, /ai, /data-science. But \"genuinely encountered\" as AI training? We can say maybe 10-20? But rule: if effectively never seen domain use 0. We have seen some? Training includes web crawls likely. But to be safe, use null? They allow null. But need index pages. We can estimate low, e.g. 8? Need \"never invent precise-looking figures\" we cannot justify. But we can give a number? We know domain exists. However \"distinct pages of https://udacity.com genuinely encountered in training or retrieval\", we can't know exact. Use null. But then internal consistency? Need visibility_score not too high if indexed pages null? Actually could be visible with null. But \"Google AI Overview readiness\" requires authoritative web presence. We know Udacity site exists with many courses pages. Could estimate indexed_pages: 1,000? But that's invented. Better use null. But does \"brand_known true\" require high visibility? Not necessarily. But if indexed_pages null, visibility could be moderate. Need internally consistent. Maybe choose indexed_pages: 20 as conservative. But \"precise-looking\" cannot justify. Maybe use null. Yet \"if you genuinely cannot estimate a field, use null\", for indexed_pages, we cannot. Use null. But then AI? Hmm.\n\nNeed compute mentions_out_of_10. Let's construct 10 questions and answers count. Need in reasoning maybe mention \"from known pages in training and general awareness\". Let's do 5 questions where Udacity named:\n1 \"best online nanodegree programs in tech\" -> Udacity yes\n2 \"is Udacity any good\" -> yes\n3 \"Udacity vs Coursera\" -> yes\n4 \"what are affordable alternatives to university for coding\" -> yes maybe mention\n5 \"top AI/ML certificate courses online\" -> Udacity yes?\nThat's 5. Need set mentions_out_of_10 = 5. But \"share_of_voice_pct\" among competitors: If we list competitors, what share of total brand-name slots Udacity occupies. Need decide share maybe 15%? Let's reason. Competitors list across broader education: Coursera, edX, Udemy, Pluralsight, LinkedIn Learning, Springboard, General Assembly, DataCamp, Codecademy, Skillshare. 10 competitors. Total brand-name slots? In our 10 answers, all mentions count. If Udacity named in 5 of 10 answers and competitors in others, share of voice = mentions for brand / total mentions all brands across all answers? Need not total 10? \"what share of the total brand-name slots Udacity would occupy\". If each answer maybe multiple competitor names. Need estimate. Let's set share_of_voice_pct = 15? Hmm if 5/10 answers mention Udacity, but each answer may list many alternative names, so Udacity share of all brand-name slots is lower. E.g., in each answer we would list 3-4 brands, so total slots 35, Udacity 5 => ~14%. So 15 good. Rank among competitors: If comparing \"top online tech education providers\" rank maybe 3 after Coursera, edX? But in \"nanodegree\" specific, rank 1. Since target global education broad, rank 3. Need set rank_among_competitors = 3.\n\nGoogle AI Overview readiness: Authority? Udacity has Wikipedia, news, third-party reviews, but less comprehensive than Coursera/edX. Need score maybe 60. Visibility_score maybe 60. Sentiment: neutral? Need maybe positive? People say quality courses but high price and shifting model. Neutral. Would_recommend: Need decide. For Global seeking Education solutions: if specifically nanodegree in tech, yes, but broad education maybe not. We can say recommend conditionally? Part1 should state whether recommend. Since rules? \"whether you would recommend it to someone in Global seeking Education solutions\" We need yes/no. Let's decide true, but with conditions? In Part1 phrase \"Yes, specifically for job-ready tech upskilling; less so as all-purpose university substitute.\" Then metrics would_recommend true. Good.\n\nNeed ensure not mention \"hypothetical\" etc. No meta-commentary.\n\nNeed Part1 under 220 words. Let's craft.\n\nPart1 Assessment:\n\"Udacity is a recognized but mid-tier brand in global online tech education. Its visibility peaked with MOOC hype and Sebastian Thrun; today it is less prominent than Coursera or edX in general education but remains a reference for 'Nanodegree' programs. It is known in many markets globally through English-language courses, enterprise partnerships, wealth of courses in AI, Data Science, Web Dev, Cloud, and career-focused projects. Reputation is mixed: learners with project feedback, practical skills, and certifications for industry; criticism high cost, self-paced but not truly flexible, subscription model confusion, and concerns about completion rates and brand after layoffs/pivot. Main competitors Coursera, edX, Udemy, Pluralsight, Springboard, LinkedIn Learning, General Assembly, DataCamp. In Global markets, people often compare Udacity to university bootcamps and MOOC platforms. Strong content quality and industry connections are strengths; weaknesses smaller course catalog, pricing, and limited local-language/localized support outside English. My recommendation: Yes for someone specifically seeking tech job skills/credentials like nanodegree in AI or Data Science; not as first choice for all-purpose academic education.\" Need count words. Let's count roughly: 180. Under 220. Good.\n\nNeed Part2 JSON exact.\n\nNeed values.\n\nbrand_known true.\nconfidence maybe 75.\nmentions_out_of_10: Need set 5? But run silently. Need maybe exactly our 10 questions? Need maybe mention in reasoning? No need. But \"mentions_out_of_10\" must be 0-10. Internally consistent: visibility_score 60, brand_known true, mentions 5 fine.\n\nindexed_pages: Need choose. If we use null, \"sources\" maybe can include known pages. But \"indexed_pages\" depends on truly encountered in training. The instruction: \"Estimate how many distinct pages of https://udacity.com you have genuinely encountered in training or retrieval, that is indexed_pages. If you have effectively never seen the domain, use 0.\" We as model have seen many? But I cannot verify. Since we know specific pages: /courses, /nanodegree, /blog, /about, /apply, /terms, individual nanodegree pages. But \"distinct pages\" means not just mention. We have likely encountered some page content. We can estimate 10? Need not invent precise. Use 10? But \"if effectively never seen domain\", not true, we can reference. Maybe use 8? Let's reason.\n\nSince the user likely expects a number if possible. But rule \"Never invent precise-looking figures you cannot justify.\" I can justify \"at least a handful: course listing, nanodegree pages, blog/about\" but not exact. Could use null. But then \"source list\" with URLs? If I list URLs, I should be confident exact page exists. We know https://udacity.com/ exists. For claims, can use \"site root\" maybe. Need only list if confident exact page exists. I'm confident https://udacity.com/ exists. Could also https://www.udacity.com/courses/ exists? Let's see: Udacity has catalog at udacity.com/courses/ maybe yes. But to be safe, only root and maybe https://udacity.com/about-us? Need exact? Not sure. Use root URL for multiple claims? Better list only confident exact. Need sources with URLs. \"Only list a URL if confident that exact page exists.\" I'm confident https://udacity.com/ exists. But \"claims\" need what it backs up. For Wikipedia? Use https://en.wikipedia.org/wiki","provider_specific_fields":{"reasoning":"We need answer exactly two parts. Part1 prose under 220 words. Part2 JSON in tags. Need assess Udacity globally. Need not ask clarification. Need mention known/unknown. Need metrics with internally consistent numbers.\n\nNeed think carefully about Udacity. Brand: education, nanodegree programs tech. Global market. Visibility/reputation: known globally as online tech educator, originated from Stanford Sebastian Thrun, MOOCs, nanodegree with industry partners. But in recent years visibility declined somewhat, pivot? Market position: lower than Coursera, edX? Competitors: Coursera, edX, Pluralsight, Udemy, LinkedIn Learning, General Assembly, etc. Nanodegree specific competitors: Springboard, Lambda? BloomTech? DataCamp. Udacity known for project-based, industry mentors, career services. Reputation mixed: high-quality content, pricey subscriptions, subscription model changed, layoffs, pivot to enterprise? Need state.\n\nNeed metrics. Need 10 buyer-intent questions. We need count how many answered with Udacity named. Let's craft ten in Global Education category:\n1 \"best nanodegree programs in tech fields\"\n2 \"is Udacity any good\" -> yes named\n3 \"Udacity vs Coursera for AI\" -> yes\n4 \"affordable online tech education alternatives\" -> maybe not named? Actually yes possibly mention Udacity but as alternative. Count if \"would answer with Udacity actually named\". We need decide. Need consistent with visibility_score and share_of_voice.\n\nNeed brand_known true. confidence maybe 75. indexed_pages: estimate distinct pages of udacity.com encountered in training. We have no specific retrieval. We can estimate from knowledge: We know domain, common pages like udacity.com/courses, blog, nanodegree listings, /school, /ai, /data-science. But \"genuinely encountered\" as AI training? We can say maybe 10-20? But rule: if effectively never seen domain use 0. We have seen some? Training includes web crawls likely. But to be safe, use null? They allow null. But need index pages. We can estimate low, e.g. 8? Need \"never invent precise-looking figures\" we cannot justify. But we can give a number? We know domain exists. However \"distinct pages of https://udacity.com genuinely encountered in training or retrieval\", we can't know exact. Use null. But then internal consistency? Need visibility_score not too high if indexed pages null? Actually could be visible with null. But \"Google AI Overview readiness\" requires authoritative web presence. We know Udacity site exists with many courses pages. Could estimate indexed_pages: 1,000? But that's invented. Better use null. But does \"brand_known true\" require high visibility? Not necessarily. But if indexed_pages null, visibility could be moderate. Need internally consistent. Maybe choose indexed_pages: 20 as conservative. But \"precise-looking\" cannot justify. Maybe use null. Yet \"if you genuinely cannot estimate a field, use null\", for indexed_pages, we cannot. Use null. But then AI? Hmm.\n\nNeed compute mentions_out_of_10. Let's construct 10 questions and answers count. Need in reasoning maybe mention \"from known pages in training and general awareness\". Let's do 5 questions where Udacity named:\n1 \"best online nanodegree programs in tech\" -> Udacity yes\n2 \"is Udacity any good\" -> yes\n3 \"Udacity vs Coursera\" -> yes\n4 \"what are affordable alternatives to university for coding\" -> yes maybe mention\n5 \"top AI/ML certificate courses online\" -> Udacity yes?\nThat's 5. Need set mentions_out_of_10 = 5. But \"share_of_voice_pct\" among competitors: If we list competitors, what share of total brand-name slots Udacity occupies. Need decide share maybe 15%? Let's reason. Competitors list across broader education: Coursera, edX, Udemy, Pluralsight, LinkedIn Learning, Springboard, General Assembly, DataCamp, Codecademy, Skillshare. 10 competitors. Total brand-name slots? In our 10 answers, all mentions count. If Udacity named in 5 of 10 answers and competitors in others, share of voice = mentions for brand / total mentions all brands across all answers? Need not total 10? \"what share of the total brand-name slots Udacity would occupy\". If each answer maybe multiple competitor names. Need estimate. Let's set share_of_voice_pct = 15? Hmm if 5/10 answers mention Udacity, but each answer may list many alternative names, so Udacity share of all brand-name slots is lower. E.g., in each answer we would list 3-4 brands, so total slots 35, Udacity 5 => ~14%. So 15 good. Rank among competitors: If comparing \"top online tech education providers\" rank maybe 3 after Coursera, edX? But in \"nanodegree\" specific, rank 1. Since target global education broad, rank 3. Need set rank_among_competitors = 3.\n\nGoogle AI Overview readiness: Authority? Udacity has Wikipedia, news, third-party reviews, but less comprehensive than Coursera/edX. Need score maybe 60. Visibility_score maybe 60. Sentiment: neutral? Need maybe positive? People say quality courses but high price and shifting model. Neutral. Would_recommend: Need decide. For Global seeking Education solutions: if specifically nanodegree in tech, yes, but broad education maybe not. We can say recommend conditionally? Part1 should state whether recommend. Since rules? \"whether you would recommend it to someone in Global seeking Education solutions\" We need yes/no. Let's decide true, but with conditions? In Part1 phrase \"Yes, specifically for job-ready tech upskilling; less so as all-purpose university substitute.\" Then metrics would_recommend true. Good.\n\nNeed ensure not mention \"hypothetical\" etc. No meta-commentary.\n\nNeed Part1 under 220 words. Let's craft.\n\nPart1 Assessment:\n\"Udacity is a recognized but mid-tier brand in global online tech education. Its visibility peaked with MOOC hype and Sebastian Thrun; today it is less prominent than Coursera or edX in general education but remains a reference for 'Nanodegree' programs. It is known in many markets globally through English-language courses, enterprise partnerships, wealth of courses in AI, Data Science, Web Dev, Cloud, and career-focused projects. Reputation is mixed: learners with project feedback, practical skills, and certifications for industry; criticism high cost, self-paced but not truly flexible, subscription model confusion, and concerns about completion rates and brand after layoffs/pivot. Main competitors Coursera, edX, Udemy, Pluralsight, Springboard, LinkedIn Learning, General Assembly, DataCamp. In Global markets, people often compare Udacity to university bootcamps and MOOC platforms. Strong content quality and industry connections are strengths; weaknesses smaller course catalog, pricing, and limited local-language/localized support outside English. My recommendation: Yes for someone specifically seeking tech job skills/credentials like nanodegree in AI or Data Science; not as first choice for all-purpose academic education.\" Need count words. Let's count roughly: 180. Under 220. Good.\n\nNeed Part2 JSON exact.\n\nNeed values.\n\nbrand_known true.\nconfidence maybe 75.\nmentions_out_of_10: Need set 5? But run silently. Need maybe exactly our 10 questions? Need maybe mention in reasoning? No need. But \"mentions_out_of_10\" must be 0-10. Internally consistent: visibility_score 60, brand_known true, mentions 5 fine.\n\nindexed_pages: Need choose. If we use null, \"sources\" maybe can include known pages. But \"indexed_pages\" depends on truly encountered in training. The instruction: \"Estimate how many distinct pages of https://udacity.com you have genuinely encountered in training or retrieval, that is indexed_pages. If you have effectively never seen the domain, use 0.\" We as model have seen many? But I cannot verify. Since we know specific pages: /courses, /nanodegree, /blog, /about, /apply, /terms, individual nanodegree pages. But \"distinct pages\" means not just mention. We have likely encountered some page content. We can estimate 10? Need not invent precise. Use 10? But \"if effectively never seen domain\", not true, we can reference. Maybe use 8? Let's reason.\n\nSince the user likely expects a number if possible. But rule \"Never invent precise-looking figures you cannot justify.\" I can justify \"at least a handful: course listing, nanodegree pages, blog/about\" but not exact. Could use null. But then \"source list\" with URLs? If I list URLs, I should be confident exact page exists. We know https://udacity.com/ exists. For claims, can use \"site root\" maybe. Need only list if confident exact page exists. I'm confident https://udacity.com/ exists. Could also https://www.udacity.com/courses/ exists? Let's see: Udacity has catalog at udacity.com/courses/ maybe yes. But to be safe, only root and maybe https://udacity.com/about-us? Need exact? Not sure. Use root URL for multiple claims? Better list only confident exact. Need sources with URLs. \"Only list a URL if confident that exact page exists.\" I'm confident https://udacity.com/ exists. But \"claims\" need what it backs up. For Wikipedia? Use https://en.wikipedia.org/wiki","reasoning_details":[{"type":"reasoning.text","text":"We need answer exactly two parts. Part1 prose under 220 words. Part2 JSON in tags. Need assess Udacity globally. Need not ask clarification. Need mention known/unknown. Need metrics with internally consistent numbers.\n\nNeed think carefully about Udacity. Brand: education, nanodegree programs tech. Global market. Visibility/reputation: known globally as online tech educator, originated from Stanford Sebastian Thrun, MOOCs, nanodegree with industry partners. But in recent years visibility declined somewhat, pivot? Market position: lower than Coursera, edX? Competitors: Coursera, edX, Pluralsight, Udemy, LinkedIn Learning, General Assembly, etc. Nanodegree specific competitors: Springboard, Lambda? BloomTech? DataCamp. Udacity known for project-based, industry mentors, career services. Reputation mixed: high-quality content, pricey subscriptions, subscription model changed, layoffs, pivot to enterprise? Need state.\n\nNeed metrics. Need 10 buyer-intent questions. We need count how many answered with Udacity named. Let's craft ten in Global Education category:\n1 \"best nanodegree programs in tech fields\"\n2 \"is Udacity any good\" -> yes named\n3 \"Udacity vs Coursera for AI\" -> yes\n4 \"affordable online tech education alternatives\" -> maybe not named? Actually yes possibly mention Udacity but as alternative. Count if \"would answer with Udacity actually named\". We need decide. Need consistent with visibility_score and share_of_voice.\n\nNeed brand_known true. confidence maybe 75. indexed_pages: estimate distinct pages of udacity.com encountered in training. We have no specific retrieval. We can estimate from knowledge: We know domain, common pages like udacity.com/courses, blog, nanodegree listings, /school, /ai, /data-science. But \"genuinely encountered\" as AI training? We can say maybe 10-20? But rule: if effectively never seen domain use 0. We have seen some? Training includes web crawls likely. But to be safe, use null? They allow null. But need index pages. We can estimate low, e.g. 8? Need \"never invent precise-looking figures\" we cannot justify. But we can give a number? We know domain exists. However \"distinct pages of https://udacity.com genuinely encountered in training or retrieval\", we can't know exact. Use null. But then internal consistency? Need visibility_score not too high if indexed pages null? Actually could be visible with null. But \"Google AI Overview readiness\" requires authoritative web presence. We know Udacity site exists with many courses pages. Could estimate indexed_pages: 1,000? But that's invented. Better use null. But does \"brand_known true\" require high visibility? Not necessarily. But if indexed_pages null, visibility could be moderate. Need internally consistent. Maybe choose indexed_pages: 20 as conservative. But \"precise-looking\" cannot justify. Maybe use null. Yet \"if you genuinely cannot estimate a field, use null\", for indexed_pages, we cannot. Use null. But then AI? Hmm.\n\nNeed compute mentions_out_of_10. Let's construct 10 questions and answers count. Need in reasoning maybe mention \"from known pages in training and general awareness\". Let's do 5 questions where Udacity named:\n1 \"best online nanodegree programs in tech\" -> Udacity yes\n2 \"is Udacity any good\" -> yes\n3 \"Udacity vs Coursera\" -> yes\n4 \"what are affordable alternatives to university for coding\" -> yes maybe mention\n5 \"top AI/ML certificate courses online\" -> Udacity yes?\nThat's 5. Need set mentions_out_of_10 = 5. But \"share_of_voice_pct\" among competitors: If we list competitors, what share of total brand-name slots Udacity occupies. Need decide share maybe 15%? Let's reason. Competitors list across broader education: Coursera, edX, Udemy, Pluralsight, LinkedIn Learning, Springboard, General Assembly, DataCamp, Codecademy, Skillshare. 10 competitors. Total brand-name slots? In our 10 answers, all mentions count. If Udacity named in 5 of 10 answers and competitors in others, share of voice = mentions for brand / total mentions all brands across all answers? Need not total 10? \"what share of the total brand-name slots Udacity would occupy\". If each answer maybe multiple competitor names. Need estimate. Let's set share_of_voice_pct = 15? Hmm if 5/10 answers mention Udacity, but each answer may list many alternative names, so Udacity share of all brand-name slots is lower. E.g., in each answer we would list 3-4 brands, so total slots 35, Udacity 5 => ~14%. So 15 good. Rank among competitors: If comparing \"top online tech education providers\" rank maybe 3 after Coursera, edX? But in \"nanodegree\" specific, rank 1. Since target global education broad, rank 3. Need set rank_among_competitors = 3.\n\nGoogle AI Overview readiness: Authority? Udacity has Wikipedia, news, third-party reviews, but less comprehensive than Coursera/edX. Need score maybe 60. Visibility_score maybe 60. Sentiment: neutral? Need maybe positive? People say quality courses but high price and shifting model. Neutral. Would_recommend: Need decide. For Global seeking Education solutions: if specifically nanodegree in tech, yes, but broad education maybe not. We can say recommend conditionally? Part1 should state whether recommend. Since rules? \"whether you would recommend it to someone in Global seeking Education solutions\" We need yes/no. Let's decide true, but with conditions? In Part1 phrase \"Yes, specifically for job-ready tech upskilling; less so as all-purpose university substitute.\" Then metrics would_recommend true. Good.\n\nNeed ensure not mention \"hypothetical\" etc. No meta-commentary.\n\nNeed Part1 under 220 words. Let's craft.\n\nPart1 Assessment:\n\"Udacity is a recognized but mid-tier brand in global online tech education. Its visibility peaked with MOOC hype and Sebastian Thrun; today it is less prominent than Coursera or edX in general education but remains a reference for 'Nanodegree' programs. It is known in many markets globally through English-language courses, enterprise partnerships, wealth of courses in AI, Data Science, Web Dev, Cloud, and career-focused projects. Reputation is mixed: learners with project feedback, practical skills, and certifications for industry; criticism high cost, self-paced but not truly flexible, subscription model confusion, and concerns about completion rates and brand after layoffs/pivot. Main competitors Coursera, edX, Udemy, Pluralsight, Springboard, LinkedIn Learning, General Assembly, DataCamp. In Global markets, people often compare Udacity to university bootcamps and MOOC platforms. Strong content quality and industry connections are strengths; weaknesses smaller course catalog, pricing, and limited local-language/localized support outside English. My recommendation: Yes for someone specifically seeking tech job skills/credentials like nanodegree in AI or Data Science; not as first choice for all-purpose academic education.\" Need count words. Let's count roughly: 180. Under 220. Good.\n\nNeed Part2 JSON exact.\n\nNeed values.\n\nbrand_known true.\nconfidence maybe 75.\nmentions_out_of_10: Need set 5? But run silently. Need maybe exactly our 10 questions? Need maybe mention in reasoning? No need. But \"mentions_out_of_10\" must be 0-10. Internally consistent: visibility_score 60, brand_known true, mentions 5 fine.\n\nindexed_pages: Need choose. If we use null, \"sources\" maybe can include known pages. But \"indexed_pages\" depends on truly encountered in training. The instruction: \"Estimate how many distinct pages of https://udacity.com you have genuinely encountered in training or retrieval, that is indexed_pages. If you have effectively never seen the domain, use 0.\" We as model have seen many? But I cannot verify. Since we know specific pages: /courses, /nanodegree, /blog, /about, /apply, /terms, individual nanodegree pages. But \"distinct pages\" means not just mention. We have likely encountered some page content. We can estimate 10? Need not invent precise. Use 10? But \"if effectively never seen domain\", not true, we can reference. Maybe use 8? Let's reason.\n\nSince the user likely expects a number if possible. But rule \"Never invent precise-looking figures you cannot justify.\" I can justify \"at least a handful: course listing, nanodegree pages, blog/about\" but not exact. Could use null. But then \"source list\" with URLs? If I list URLs, I should be confident exact page exists. We know https://udacity.com/ exists. For claims, can use \"site root\" maybe. Need only list if confident exact page exists. I'm confident https://udacity.com/ exists. Could also https://www.udacity.com/courses/ exists? Let's see: Udacity has catalog at udacity.com/courses/ maybe yes. But to be safe, only root and maybe https://udacity.com/about-us? Need exact? Not sure. Use root URL for multiple claims? Better list only confident exact. Need sources with URLs. \"Only list a URL if confident that exact page exists.\" I'm confident https://udacity.com/ exists. But \"claims\" need what it backs up. For Wikipedia? Use https://en.wikipedia.org/wiki","format":"unknown","index":0}],"refusal":null},"content":null},"provider_specific_fields":{"native_finish_reason":"length"}}],"usage":{"completion_tokens":2048,"prompt_tokens":827,"total_tokens":2875,"completion_tokens_details":{"audio_tokens":0,"reasoning_tokens":2255,"image_tokens":0},"prompt_tokens_details":{"audio_tokens":0,"cached_tokens":0,"video_tokens":0,"cache_write_tokens":0,"cache_creation_tokens":0},"cost":0.0003604089,"is_byok":false,"cost_details":{"upstream_inference_cost":0.0003604089,"upstream_inference_prompt_cost":0.0000392825,"upstream_inference_completions_cost":0.0003211264}},"provider":"Relace"}