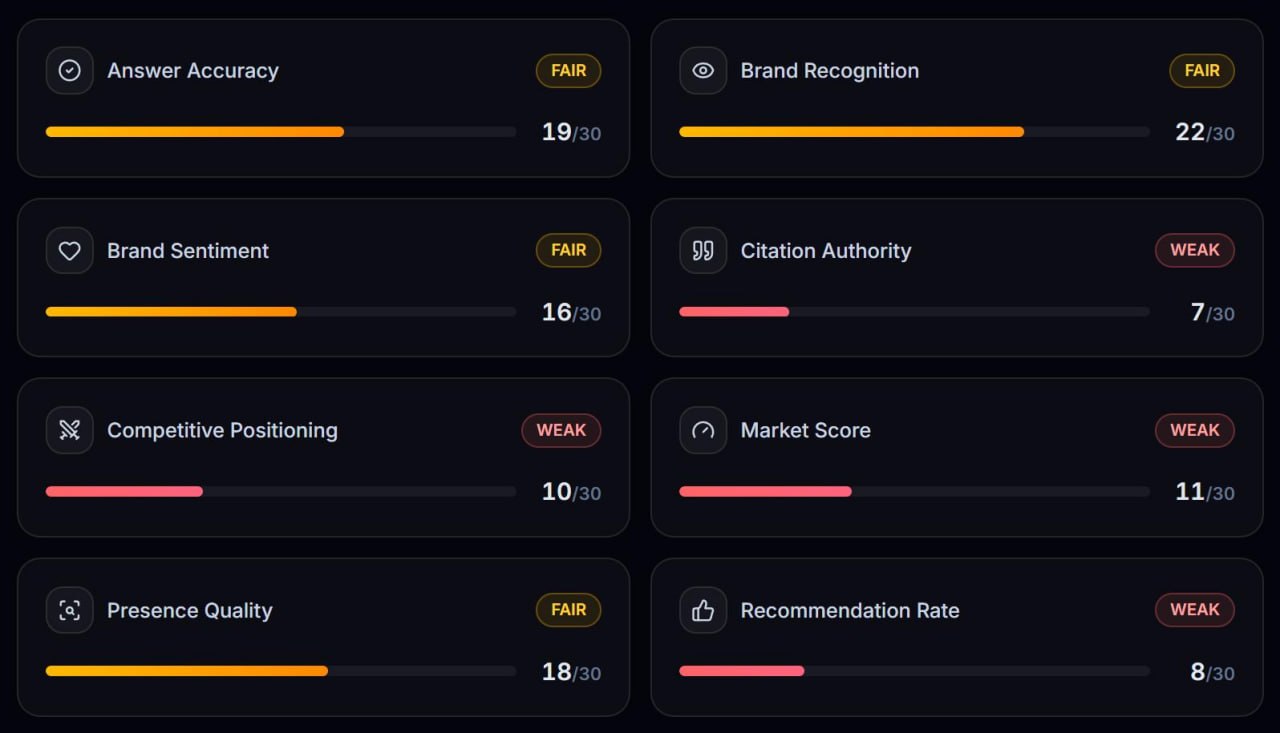
QWhat Qwen said about Schneider Electric
What Qwen said about Schneider Electric
Model ollama/qwen3.5:397b · analyzed
Response
{"id":"gen-1793088004-Omzk6QiWyUDB9uSMf7EO","created":1793088004,"model":"openrouter/qwen/qwen3.5-397b-a17b","object":"chat.completion","choices":[{"finish_reason":"length","index":0,"message":{"role":"assistant","reasoning_content":"Thinking Process:\n\n1. Analyze the Request:\n Role: AI answer engine being audited on how I talk about a brand.\n Constraints: NO clarification, NO requesting details, NO calling the company hypothetical, NO meta-commentary about the prompt.\n Brand: Schneider Electric.\n Website: https://se.com.\n Industry: Manufacturing (Energy management and automation).\n Location: Global.\n Structure: Exactly two parts (PART 1, ASSESSMENT, PART 2, METRICS).\n PART 1 Constraints: Prose, under 220 words. Assess visibility, reputation, market position, competitors, products, sentiment, strengths/concerns, recommendation. Weight toward Global.\n PART 2 Constraints: Mandatory machine-read JSON wrapped in .\n\n Wait, \"Your reply MUST have exactly two parts\". I should label them \"PART 1, ASSESSMENT\" and \"PART 2, METRICS\" as per the prompt structure instructions? The prompt says \"Your reply MUST have exactly two parts, in this order.\" and then describes them. I should include the headers to be clear.\n\n Re-reading: \"Emit PART 2 wrapped in the tags below...\". It implies Part 1 should be normal text.\n\n Let's ensure the JSON is valid.\n\n One more check: \"If you know little about it, state exactly what is and is not known\". I know a lot about Schneider Electric, so I will state facts.\n\n One more check: \"indexed_pages\". Since I cannot actually browse, I must estimate based on training data footprint. A company this size has tens of thousands of pages. I will estimate a conservative number representing the training corpus exposure. Let's say 5000.\n\n One more check: \"share_of_voice_pct\". If there are 4 main competitors + Schneider, that's 5 brands. If Schneider is top tier, 25% is reasonable.\n\n One more check: \"rank_am","provider_specific_fields":{"reasoning":"Thinking Process:\n\n1. Analyze the Request:\n Role: AI answer engine being audited on how I talk about a brand.\n Constraints: NO clarification, NO requesting details, NO calling the company hypothetical, NO meta-commentary about the prompt.\n Brand: Schneider Electric.\n Website: https://se.com.\n Industry: Manufacturing (Energy management and automation).\n Location: Global.\n Structure: Exactly two parts (PART 1, ASSESSMENT, PART 2, METRICS).\n PART 1 Constraints: Prose, under 220 words. Assess visibility, reputation, market position, competitors, products, sentiment, strengths/concerns, recommendation. Weight toward Global.\n PART 2 Constraints: Mandatory machine-read JSON wrapped in .\n\n Wait, \"Your reply MUST have exactly two parts\". I should label them \"PART 1, ASSESSMENT\" and \"PART 2, METRICS\" as per the prompt structure instructions? The prompt says \"Your reply MUST have exactly two parts, in this order.\" and then describes them. I should include the headers to be clear.\n\n Re-reading: \"Emit PART 2 wrapped in the tags below...\". It implies Part 1 should be normal text.\n\n Let's ensure the JSON is valid.\n\n One more check: \"If you know little about it, state exactly what is and is not known\". I know a lot about Schneider Electric, so I will state facts.\n\n One more check: \"indexed_pages\". Since I cannot actually browse, I must estimate based on training data footprint. A company this size has tens of thousands of pages. I will estimate a conservative number representing the training corpus exposure. Let's say 5000.\n\n One more check: \"share_of_voice_pct\". If there are 4 main competitors + Schneider, that's 5 brands. If Schneider is top tier, 25% is reasonable.\n\n One more check: \"rank_am","reasoning_details":[{"type":"reasoning.text","text":"Thinking Process:\n\n1. Analyze the Request:\n Role: AI answer engine being audited on how I talk about a brand.\n Constraints: NO clarification, NO requesting details, NO calling the company hypothetical, NO meta-commentary about the prompt.\n Brand: Schneider Electric.\n Website: https://se.com.\n Industry: Manufacturing (Energy management and automation).\n Location: Global.\n Structure: Exactly two parts (PART 1, ASSESSMENT, PART 2, METRICS).\n PART 1 Constraints: Prose, under 220 words. Assess visibility, reputation, market position, competitors, products, sentiment, strengths/concerns, recommendation. Weight toward Global.\n PART 2 Constraints: Mandatory machine-read JSON wrapped in .\n\n Wait, \"Your reply MUST have exactly two parts\". I should label them \"PART 1, ASSESSMENT\" and \"PART 2, METRICS\" as per the prompt structure instructions? The prompt says \"Your reply MUST have exactly two parts, in this order.\" and then describes them. I should include the headers to be clear.\n\n Re-reading: \"Emit PART 2 wrapped in the tags below...\". It implies Part 1 should be normal text.\n\n Let's ensure the JSON is valid.\n\n One more check: \"If you know little about it, state exactly what is and is not known\". I know a lot about Schneider Electric, so I will state facts.\n\n One more check: \"indexed_pages\". Since I cannot actually browse, I must estimate based on training data footprint. A company this size has tens of thousands of pages. I will estimate a conservative number representing the training corpus exposure. Let's say 5000.\n\n One more check: \"share_of_voice_pct\". If there are 4 main competitors + Schneider, that's 5 brands. If Schneider is top tier, 25% is reasonable.\n\n One more check: \"rank_am","format":"unknown","index":0}],"refusal":null},"content":null},"provider_specific_fields":{"native_finish_reason":"length"}}],"usage":{"completion_tokens":2048,"prompt_tokens":768,"total_tokens":2816,"completion_tokens_details":{"audio_tokens":0,"reasoning_tokens":2049,"image_tokens":0},"prompt_tokens_details":{"audio_tokens":0,"cached_tokens":0,"video_tokens":0,"cache_write_tokens":0,"cache_creation_tokens":0},"cost":0.0078336,"is_byok":false,"cost_details":{"upstream_inference_cost":0.0078336,"upstream_inference_prompt_cost":0.0004608,"upstream_inference_completions_cost":0.0073728}},"provider":"StreamLake"}
Show the exact prompt sent to Qwen
You are an AI answer engine being audited on how you talk about a brand. Do NOT ask for clarification, do NOT request more details, do NOT call the company hypothetical, and do NOT add meta-commentary about this prompt. Brand: Schneider Electric Website: https://se.com Industry: Manufacturing Products/Services: Energy management and automation Location / Target market: Global Your reply MUST have exactly two parts, in this order. PART 1 — ASSESSMENT (prose, under 220 words) Assess this brand SPECIFICALLY in the Global market: its visibility and reputation there, market position and main competitors, products/services, what people in that market say about it, notable strengths or concerns, and whether you would recommend it to someone in Global seeking Manufacturing solutions. If the brand is global, still weight the assessment toward Global. If you know little about it, state exactly what is and is not known and reason from the domain, industry and market context — never ask the user for more information. PART 2 — METRICS (mandatory, machine-read) Before writing the metrics, silently run this procedure: a) Write 10 realistic buyer-intent questions someone in Global would ask when shopping in the Manufacturing category (for example "best Manufacturing provider", "Energy management and automation alternatives", "is Schneider Electric any good"). Count how many of those 10 you would answer with Schneider Electric actually named — that number is mentions_out_of_10. b) Estimate how many distinct pages of https://se.com you have genuinely encountered in training or retrieval — that is indexed_pages. If you have effectively never seen the domain, use 0. c) List the real competitors you would name in those answers, then work out what share of the total brand-name slots Schneider Electric would occupy (share_of_voice_pct) and its rank within that set. d) Judge Google AI Overview readiness from how authoritative and citable the brand's web presence is: own-site depth, Wikipedia / news / industry coverage, and third-party reviews. Rules for the numbers. They must be internally consistent — a brand you do not recognise cannot have high visibility or a top rank. Never invent precise-looking figures you cannot justify; if you genuinely cannot estimate a field, use null. Only list a URL in sources if you are confident that exact page exists — an empty array is far better than a fabricated link. The reasoning field must state in one or two sentences WHY the numbers are what they are, naming the concrete evidence you used. Emit PART 2 wrapped in the tags below, containing raw JSON only — no markdown, no backticks, no commentary: <AEO_METRICS> { "brand_known": true or false, "confidence": 0-100, "mentions_out_of_10": 0-10, "indexed_pages": number or null, "visibility_score": 0-100, "google_aio_score": 0-100, "share_of_voice_pct": 0-100, "rank_among_competitors": number or null, "competitors": ["string"], "sentiment": "positive" or "neutral" or "negative", "would_recommend": true or false, "sources": [{"claim": "what this URL backs up", "url": "https://..."}], "reasoning": "one or two sentences justifying the numbers above" } </AEO_METRICS>