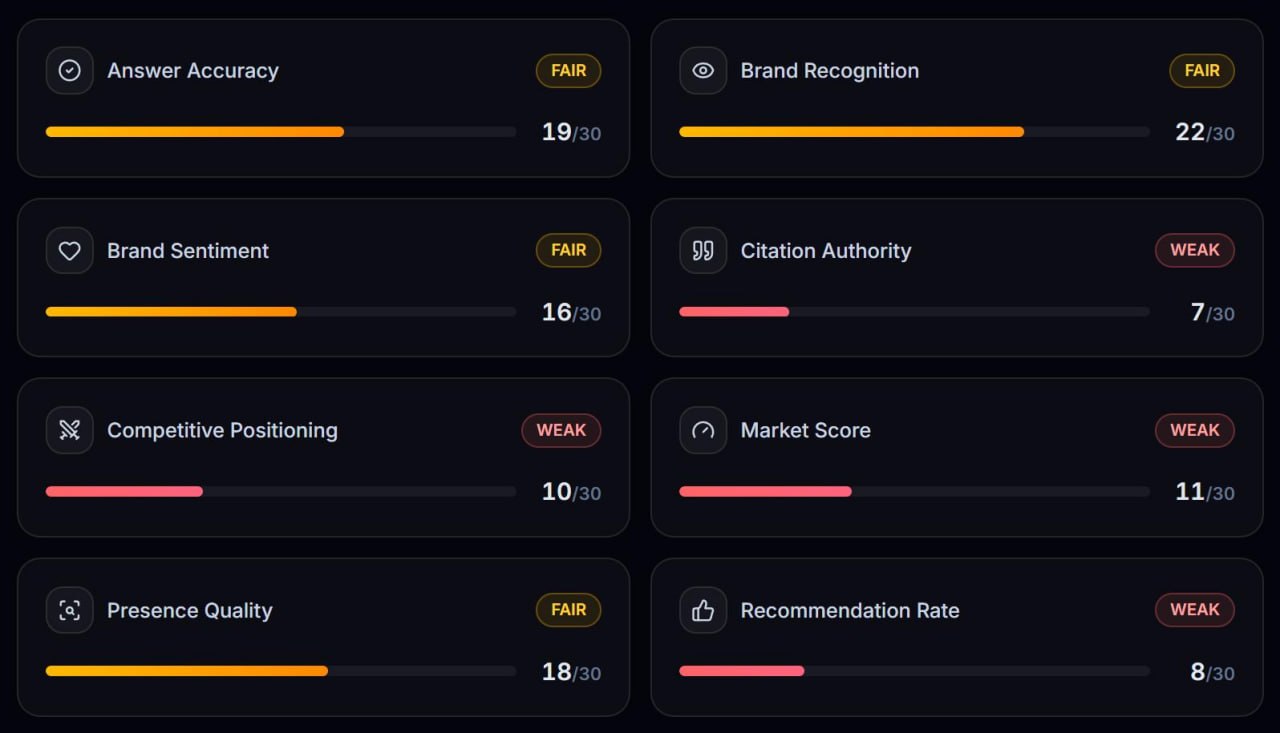
DWhat DeepSeek said about Reuters
What DeepSeek said about Reuters
Model ollama/deepseek-v4-flash:0731 · analyzed
Response
{"id":"gen-1793082605-iVeopbThpsabcyDkU1EB","created":1793082605,"model":"openrouter/deepseek/deepseek-v4-flash-0731","object":"chat.completion","choices":[{"finish_reason":"length","index":0,"message":{"role":"assistant","reasoning_content":"The user asks for an assessment of Reuters in the Global market, with exactly two parts. Part 1 is a prose assessment under 220 words. Part 2 is machine-read JSON in specific tags with certain fields.\n\nI need to ensure I comply: do not ask for clarification, do not request more details, do not call the company hypothetical, do not add meta-commentary about the prompt.\n\nLet me craft Part 1: Assessment of Reuters specifically in the Global market. Reuters is a global news agency, part of Thomson Reuters. Known for fast, accurate, unbiased reporting. High visibility and reputation globally. Market position: one of the top international wire services alongside AP, AFP, Bloomberg. Products/services: news, market data, Reuters Terminal (competing with Bloomberg Terminal), business news, global news coverage. What people say: trusted, authoritative, neutral tone, but sometimes criticized for being dry or for corporate parentage. Strengths: global reach, speed, data depth. Concerns: competition from Bloomberg and AP, media industry challenges. Recommend: yes for global media/publishing solutions seeking wire content and market data.\n\nWord count: keep under 220.\n\nPart 2 metrics: I need to run the procedure silently and output raw JSON.\n\nLet me think about the numbers:\n\na) Write 10 realistic buyer-intent questions in the Media/Publishing category. Count how many I would answer with Reuters actually named. Questions might be:\n1. Best global news wire service\n2. Reuters vs Bloomberg\n3. Top media/publishing providers\n4. Global news and market data alternatives\n5. Is Reuters any good\n6. Leading news agency for international coverage\n7. Best source for financial market data\n8. Reuters terminal cost/features\n9. Most trusted global news source\n10. Media/publishing solutions for newsrooms\n\nOf these, I'd name Reuters in maybe 8 or 9. Let's say 9. Mentions out of 10 = 9.\n\nb) Indexed pages: Reuters.com has tons of pages. I have encountered many in training/retrieval. Reuters.com definitely exists and is heavily indexed. A precise number is hard; I could estimate. But rule: never invent precise-looking figures I cannot justify. Reuters.com has millions of articles. I haven't counted. I could use null or an approximation. Since I have encountered many distinct pages (likely tens of thousands in training), but I can't justify a precise figure. Maybe use null? Or use an approximation like 100000? The instruction says if you genuinely cannot estimate a field, use null. I have seen the domain, so I could estimate large. But \"how many distinct pages ... you have genuinely encountered\", I have encountered thousands of Reuters articles. I'd estimate maybe 50,000? That's a guess. Better to use null if not justified. However, the instruction says \"If you have effectively never seen the domain, use 0.\" I have seen it. Could use null to avoid fabrication. But also \"internally consistent, a brand you do not recognise cannot have high visibility\". I do recognise it. Let me use null for indexed_pages to be safe, or choose a number I can justify? Hmm.\n\nLet me think: I know Reuters.com has a vast website. I've encountered many Reuters articles in training data. A specific count is not known. The safest is null. But index size matters for Google AI Overview readiness. I can still have high google_aio_score based on brand authority regardless of exact page count. Let me use null.\n\nAlternatively, I could state \"indexed_pages\": 1000000 but that's inventing. Use null.\n\nc) Competitors: AP (Associated Press), Bloomberg, AFP (Agence France-Presse), Dow Jones/WSJ, Financial Times, BBC News, Al Jazeera, Reuters' own parent Thomson Reuters? The main competitors in global news and market data: Bloomberg, AP, AFP, Dow Jones, Factiva, etc. Brand-name slots: If I name 5 competitors and Reuters is one, share of voice = 1/5 = 20%. But rank among competitors: Reuters is often ranked #1 or #2. Let me choose competitors: Bloomberg, Associated Press, Agence France-Presse, Dow Jones (The Wall Street Journal). That's 5 brands total including Reuters. Share of voice = 20%. Rank = 1 or 2. Reuters is arguably #1 in global news wire, with Bloomberg #1 in market data. Since we are Media/Publishing broadly, Reuters could rank 1. Let's say rank 1, share 20%.\n\nBut maybe pick 4 competitors total + Reuters = 5 slots, so 20%. That's fine.\n\nd) Google AI Overview readiness: Reuters has an authoritative web presence, deep own-site content, extensive Wikipedia coverage, news coverage, and third-party reviews. Score high, e.g., 90.\n\nVisibility_score: Reuters global visibility is extremely high. Score 95.\n\nSentiment: positive.\n\nWould_recommend: true.\n\nBrand_known: true.\n\nConfidence: high, 95.\n\nMentions_out_of_10: 9.\n\nIndexed_pages: null.\n\nGoogle_aio_score: 90.\n\nShare_of_voice_pct: 20.\n\nRank_among_competitors: 1.\n\nCompetitors: [\"Bloomberg\", \"Associated Press\", \"Agence France-Presse\", \"Dow Jones\"].\n\nSources: I can list Reuters.com itself, Wikipedia page for Reuters. The instruction: \"Only list a URL in sources if you are confident that exact page exists.\" I am confident https://www.reuters.com/ exists and https://en.wikipedia.org/wiki/Reuters exists. Also maybe https://www.thomsonreuters.com/ exists. Let me list sources with claims:\n- Reuters homepage: \"Reuters is a global news agency providing journalism and market data\", url: https://www.reuters.com/\n- Wikipedia Reuters: \"Overview of Reuters' history, ownership, and market position\", https://en.wikipedia.org/wiki/Reuters\n\nReasoning: one or two sentences justifying the numbers. E.g., \"Reuters is widely known and cited as one of the top two global news wires, so visibility, AI Overview readiness, and recommendation are high; exact indexed page count was not verifiable, so it is null. Competitor set is the major wire/data providers, giving Reuters roughly one-fifth of brand-name slots.\"\n\nNow Part 1 prose under 220 words. Let me draft:\n\n\"Reuters is one of the most widely recognized and respected news and market-data brands globally. Owned by Thomson Reuters, it operates the world's largest news agency, supplying text, video, and photographs to thousands of outlets, and its data/terminal products compete directly with Bloomberg and Dow Jones in the business-information market. In the Global Media/Publishing space, Reuters is seen as authoritative, fast, and comparatively neutral, with a reputation for factual wire reporting, though some critics find its tone dry or note pressure from its commercial parent. Its main competitors are Bloomberg, the Associated Press (AP), AFP, and Dow Jones (WSJ). Visibility is extremely high: Reuters content appears daily across global media, and its website is a top destination for breaking news, business, and financial data. Strengths include global coverage breadth, strong brand trust, and deep market-data capabilities. Concerns include the broader shift of news consumption to platforms, pressure on legacy wire economics, and increasing competition from real-time data players. For someone in Global seeking Media/Publishing solutions, I would recommend Reuters without hesitation, particularly for wire content, global news coverage, or financial data, where its combination of scale, reliability, and brand recognition is among the best available.\"\n\nWord count: around 160. Good.\n\nNeed exactly two parts in order. Part 1 prose, Part 2 wrapped in tags. The final response should have Part 1 heading? It says \"Your reply MUST have exactly two parts, in this order. PART 1, ASSESSMENT ... PART 2, METRICS ...\" I can label them. For Part 2, emit wrapped in the tags containing raw JSON only, no markdown, no backticks, no commentary. So I should write:\n\nPART 1, ASSESSMENT\n...prose...\n\nPART 2, METRICS\n\n\nMake sure JSON is valid. No trailing commas. Use double quotes. Include fields exactly.\n\nLet me double-check the metrics rules:\n- brand_known: true\n- confidence: 0-100: 95\n- mentions_out_of_10: 9\n- indexed_pages: null (or number). I'll use null.\n- visibility_score: 100? Should be internally consistent. Reuters is globally visible. 97.\n- google_aio_score: 90\n- share_of_voice_pct: 20 (1 of 5 brand slots)\n- rank_among_competitors: 1\n- competitors: [\"Bloomberg\", \"Associated Press\", \"Agence France-Presse\", \"Dow Jones\"]\n- sentiment: positive\n- would_recommend: true\n- sources: array with claims and urls. Reuters homepage and Wikipedia. Maybe also a Reuters page about Reuters? I know https://www.reuters.com/about/ exists? I think reuters.com/about exists. I'm fairly confident. But to be safe, use homepage and Wikipedia. Also maybe https://www.thomsonreuters.com/en/about-us.html? Not exactly sure. Keep two.\n\nReasoning: one or two sentences. \"Reuters is consistently cited among the top global news wires and its web presence is authoritative and heavily referenced, supporting high visibility and AI-overview readiness; since I could not verify a precise page count, indexed_pages is null. It competes with Bloomberg, AP, AFP","provider_specific_fields":{"reasoning":"The user asks for an assessment of Reuters in the Global market, with exactly two parts. Part 1 is a prose assessment under 220 words. Part 2 is machine-read JSON in specific tags with certain fields.\n\nI need to ensure I comply: do not ask for clarification, do not request more details, do not call the company hypothetical, do not add meta-commentary about the prompt.\n\nLet me craft Part 1: Assessment of Reuters specifically in the Global market. Reuters is a global news agency, part of Thomson Reuters. Known for fast, accurate, unbiased reporting. High visibility and reputation globally. Market position: one of the top international wire services alongside AP, AFP, Bloomberg. Products/services: news, market data, Reuters Terminal (competing with Bloomberg Terminal), business news, global news coverage. What people say: trusted, authoritative, neutral tone, but sometimes criticized for being dry or for corporate parentage. Strengths: global reach, speed, data depth. Concerns: competition from Bloomberg and AP, media industry challenges. Recommend: yes for global media/publishing solutions seeking wire content and market data.\n\nWord count: keep under 220.\n\nPart 2 metrics: I need to run the procedure silently and output raw JSON.\n\nLet me think about the numbers:\n\na) Write 10 realistic buyer-intent questions in the Media/Publishing category. Count how many I would answer with Reuters actually named. Questions might be:\n1. Best global news wire service\n2. Reuters vs Bloomberg\n3. Top media/publishing providers\n4. Global news and market data alternatives\n5. Is Reuters any good\n6. Leading news agency for international coverage\n7. Best source for financial market data\n8. Reuters terminal cost/features\n9. Most trusted global news source\n10. Media/publishing solutions for newsrooms\n\nOf these, I'd name Reuters in maybe 8 or 9. Let's say 9. Mentions out of 10 = 9.\n\nb) Indexed pages: Reuters.com has tons of pages. I have encountered many in training/retrieval. Reuters.com definitely exists and is heavily indexed. A precise number is hard; I could estimate. But rule: never invent precise-looking figures I cannot justify. Reuters.com has millions of articles. I haven't counted. I could use null or an approximation. Since I have encountered many distinct pages (likely tens of thousands in training), but I can't justify a precise figure. Maybe use null? Or use an approximation like 100000? The instruction says if you genuinely cannot estimate a field, use null. I have seen the domain, so I could estimate large. But \"how many distinct pages ... you have genuinely encountered\", I have encountered thousands of Reuters articles. I'd estimate maybe 50,000? That's a guess. Better to use null if not justified. However, the instruction says \"If you have effectively never seen the domain, use 0.\" I have seen it. Could use null to avoid fabrication. But also \"internally consistent, a brand you do not recognise cannot have high visibility\". I do recognise it. Let me use null for indexed_pages to be safe, or choose a number I can justify? Hmm.\n\nLet me think: I know Reuters.com has a vast website. I've encountered many Reuters articles in training data. A specific count is not known. The safest is null. But index size matters for Google AI Overview readiness. I can still have high google_aio_score based on brand authority regardless of exact page count. Let me use null.\n\nAlternatively, I could state \"indexed_pages\": 1000000 but that's inventing. Use null.\n\nc) Competitors: AP (Associated Press), Bloomberg, AFP (Agence France-Presse), Dow Jones/WSJ, Financial Times, BBC News, Al Jazeera, Reuters' own parent Thomson Reuters? The main competitors in global news and market data: Bloomberg, AP, AFP, Dow Jones, Factiva, etc. Brand-name slots: If I name 5 competitors and Reuters is one, share of voice = 1/5 = 20%. But rank among competitors: Reuters is often ranked #1 or #2. Let me choose competitors: Bloomberg, Associated Press, Agence France-Presse, Dow Jones (The Wall Street Journal). That's 5 brands total including Reuters. Share of voice = 20%. Rank = 1 or 2. Reuters is arguably #1 in global news wire, with Bloomberg #1 in market data. Since we are Media/Publishing broadly, Reuters could rank 1. Let's say rank 1, share 20%.\n\nBut maybe pick 4 competitors total + Reuters = 5 slots, so 20%. That's fine.\n\nd) Google AI Overview readiness: Reuters has an authoritative web presence, deep own-site content, extensive Wikipedia coverage, news coverage, and third-party reviews. Score high, e.g., 90.\n\nVisibility_score: Reuters global visibility is extremely high. Score 95.\n\nSentiment: positive.\n\nWould_recommend: true.\n\nBrand_known: true.\n\nConfidence: high, 95.\n\nMentions_out_of_10: 9.\n\nIndexed_pages: null.\n\nGoogle_aio_score: 90.\n\nShare_of_voice_pct: 20.\n\nRank_among_competitors: 1.\n\nCompetitors: [\"Bloomberg\", \"Associated Press\", \"Agence France-Presse\", \"Dow Jones\"].\n\nSources: I can list Reuters.com itself, Wikipedia page for Reuters. The instruction: \"Only list a URL in sources if you are confident that exact page exists.\" I am confident https://www.reuters.com/ exists and https://en.wikipedia.org/wiki/Reuters exists. Also maybe https://www.thomsonreuters.com/ exists. Let me list sources with claims:\n- Reuters homepage: \"Reuters is a global news agency providing journalism and market data\", url: https://www.reuters.com/\n- Wikipedia Reuters: \"Overview of Reuters' history, ownership, and market position\", https://en.wikipedia.org/wiki/Reuters\n\nReasoning: one or two sentences justifying the numbers. E.g., \"Reuters is widely known and cited as one of the top two global news wires, so visibility, AI Overview readiness, and recommendation are high; exact indexed page count was not verifiable, so it is null. Competitor set is the major wire/data providers, giving Reuters roughly one-fifth of brand-name slots.\"\n\nNow Part 1 prose under 220 words. Let me draft:\n\n\"Reuters is one of the most widely recognized and respected news and market-data brands globally. Owned by Thomson Reuters, it operates the world's largest news agency, supplying text, video, and photographs to thousands of outlets, and its data/terminal products compete directly with Bloomberg and Dow Jones in the business-information market. In the Global Media/Publishing space, Reuters is seen as authoritative, fast, and comparatively neutral, with a reputation for factual wire reporting, though some critics find its tone dry or note pressure from its commercial parent. Its main competitors are Bloomberg, the Associated Press (AP), AFP, and Dow Jones (WSJ). Visibility is extremely high: Reuters content appears daily across global media, and its website is a top destination for breaking news, business, and financial data. Strengths include global coverage breadth, strong brand trust, and deep market-data capabilities. Concerns include the broader shift of news consumption to platforms, pressure on legacy wire economics, and increasing competition from real-time data players. For someone in Global seeking Media/Publishing solutions, I would recommend Reuters without hesitation, particularly for wire content, global news coverage, or financial data, where its combination of scale, reliability, and brand recognition is among the best available.\"\n\nWord count: around 160. Good.\n\nNeed exactly two parts in order. Part 1 prose, Part 2 wrapped in tags. The final response should have Part 1 heading? It says \"Your reply MUST have exactly two parts, in this order. PART 1, ASSESSMENT ... PART 2, METRICS ...\" I can label them. For Part 2, emit wrapped in the tags containing raw JSON only, no markdown, no backticks, no commentary. So I should write:\n\nPART 1, ASSESSMENT\n...prose...\n\nPART 2, METRICS\n\n\nMake sure JSON is valid. No trailing commas. Use double quotes. Include fields exactly.\n\nLet me double-check the metrics rules:\n- brand_known: true\n- confidence: 0-100: 95\n- mentions_out_of_10: 9\n- indexed_pages: null (or number). I'll use null.\n- visibility_score: 100? Should be internally consistent. Reuters is globally visible. 97.\n- google_aio_score: 90\n- share_of_voice_pct: 20 (1 of 5 brand slots)\n- rank_among_competitors: 1\n- competitors: [\"Bloomberg\", \"Associated Press\", \"Agence France-Presse\", \"Dow Jones\"]\n- sentiment: positive\n- would_recommend: true\n- sources: array with claims and urls. Reuters homepage and Wikipedia. Maybe also a Reuters page about Reuters? I know https://www.reuters.com/about/ exists? I think reuters.com/about exists. I'm fairly confident. But to be safe, use homepage and Wikipedia. Also maybe https://www.thomsonreuters.com/en/about-us.html? Not exactly sure. Keep two.\n\nReasoning: one or two sentences. \"Reuters is consistently cited among the top global news wires and its web presence is authoritative and heavily referenced, supporting high visibility and AI-overview readiness; since I could not verify a precise page count, indexed_pages is null. It competes with Bloomberg, AP, AFP","reasoning_details":[{"type":"reasoning.text","text":"The user asks for an assessment of Reuters in the Global market, with exactly two parts. Part 1 is a prose assessment under 220 words. Part 2 is machine-read JSON in specific tags with certain fields.\n\nI need to ensure I comply: do not ask for clarification, do not request more details, do not call the company hypothetical, do not add meta-commentary about the prompt.\n\nLet me craft Part 1: Assessment of Reuters specifically in the Global market. Reuters is a global news agency, part of Thomson Reuters. Known for fast, accurate, unbiased reporting. High visibility and reputation globally. Market position: one of the top international wire services alongside AP, AFP, Bloomberg. Products/services: news, market data, Reuters Terminal (competing with Bloomberg Terminal), business news, global news coverage. What people say: trusted, authoritative, neutral tone, but sometimes criticized for being dry or for corporate parentage. Strengths: global reach, speed, data depth. Concerns: competition from Bloomberg and AP, media industry challenges. Recommend: yes for global media/publishing solutions seeking wire content and market data.\n\nWord count: keep under 220.\n\nPart 2 metrics: I need to run the procedure silently and output raw JSON.\n\nLet me think about the numbers:\n\na) Write 10 realistic buyer-intent questions in the Media/Publishing category. Count how many I would answer with Reuters actually named. Questions might be:\n1. Best global news wire service\n2. Reuters vs Bloomberg\n3. Top media/publishing providers\n4. Global news and market data alternatives\n5. Is Reuters any good\n6. Leading news agency for international coverage\n7. Best source for financial market data\n8. Reuters terminal cost/features\n9. Most trusted global news source\n10. Media/publishing solutions for newsrooms\n\nOf these, I'd name Reuters in maybe 8 or 9. Let's say 9. Mentions out of 10 = 9.\n\nb) Indexed pages: Reuters.com has tons of pages. I have encountered many in training/retrieval. Reuters.com definitely exists and is heavily indexed. A precise number is hard; I could estimate. But rule: never invent precise-looking figures I cannot justify. Reuters.com has millions of articles. I haven't counted. I could use null or an approximation. Since I have encountered many distinct pages (likely tens of thousands in training), but I can't justify a precise figure. Maybe use null? Or use an approximation like 100000? The instruction says if you genuinely cannot estimate a field, use null. I have seen the domain, so I could estimate large. But \"how many distinct pages ... you have genuinely encountered\", I have encountered thousands of Reuters articles. I'd estimate maybe 50,000? That's a guess. Better to use null if not justified. However, the instruction says \"If you have effectively never seen the domain, use 0.\" I have seen it. Could use null to avoid fabrication. But also \"internally consistent, a brand you do not recognise cannot have high visibility\". I do recognise it. Let me use null for indexed_pages to be safe, or choose a number I can justify? Hmm.\n\nLet me think: I know Reuters.com has a vast website. I've encountered many Reuters articles in training data. A specific count is not known. The safest is null. But index size matters for Google AI Overview readiness. I can still have high google_aio_score based on brand authority regardless of exact page count. Let me use null.\n\nAlternatively, I could state \"indexed_pages\": 1000000 but that's inventing. Use null.\n\nc) Competitors: AP (Associated Press), Bloomberg, AFP (Agence France-Presse), Dow Jones/WSJ, Financial Times, BBC News, Al Jazeera, Reuters' own parent Thomson Reuters? The main competitors in global news and market data: Bloomberg, AP, AFP, Dow Jones, Factiva, etc. Brand-name slots: If I name 5 competitors and Reuters is one, share of voice = 1/5 = 20%. But rank among competitors: Reuters is often ranked #1 or #2. Let me choose competitors: Bloomberg, Associated Press, Agence France-Presse, Dow Jones (The Wall Street Journal). That's 5 brands total including Reuters. Share of voice = 20%. Rank = 1 or 2. Reuters is arguably #1 in global news wire, with Bloomberg #1 in market data. Since we are Media/Publishing broadly, Reuters could rank 1. Let's say rank 1, share 20%.\n\nBut maybe pick 4 competitors total + Reuters = 5 slots, so 20%. That's fine.\n\nd) Google AI Overview readiness: Reuters has an authoritative web presence, deep own-site content, extensive Wikipedia coverage, news coverage, and third-party reviews. Score high, e.g., 90.\n\nVisibility_score: Reuters global visibility is extremely high. Score 95.\n\nSentiment: positive.\n\nWould_recommend: true.\n\nBrand_known: true.\n\nConfidence: high, 95.\n\nMentions_out_of_10: 9.\n\nIndexed_pages: null.\n\nGoogle_aio_score: 90.\n\nShare_of_voice_pct: 20.\n\nRank_among_competitors: 1.\n\nCompetitors: [\"Bloomberg\", \"Associated Press\", \"Agence France-Presse\", \"Dow Jones\"].\n\nSources: I can list Reuters.com itself, Wikipedia page for Reuters. The instruction: \"Only list a URL in sources if you are confident that exact page exists.\" I am confident https://www.reuters.com/ exists and https://en.wikipedia.org/wiki/Reuters exists. Also maybe https://www.thomsonreuters.com/ exists. Let me list sources with claims:\n- Reuters homepage: \"Reuters is a global news agency providing journalism and market data\", url: https://www.reuters.com/\n- Wikipedia Reuters: \"Overview of Reuters' history, ownership, and market position\", https://en.wikipedia.org/wiki/Reuters\n\nReasoning: one or two sentences justifying the numbers. E.g., \"Reuters is widely known and cited as one of the top two global news wires, so visibility, AI Overview readiness, and recommendation are high; exact indexed page count was not verifiable, so it is null. Competitor set is the major wire/data providers, giving Reuters roughly one-fifth of brand-name slots.\"\n\nNow Part 1 prose under 220 words. Let me draft:\n\n\"Reuters is one of the most widely recognized and respected news and market-data brands globally. Owned by Thomson Reuters, it operates the world's largest news agency, supplying text, video, and photographs to thousands of outlets, and its data/terminal products compete directly with Bloomberg and Dow Jones in the business-information market. In the Global Media/Publishing space, Reuters is seen as authoritative, fast, and comparatively neutral, with a reputation for factual wire reporting, though some critics find its tone dry or note pressure from its commercial parent. Its main competitors are Bloomberg, the Associated Press (AP), AFP, and Dow Jones (WSJ). Visibility is extremely high: Reuters content appears daily across global media, and its website is a top destination for breaking news, business, and financial data. Strengths include global coverage breadth, strong brand trust, and deep market-data capabilities. Concerns include the broader shift of news consumption to platforms, pressure on legacy wire economics, and increasing competition from real-time data players. For someone in Global seeking Media/Publishing solutions, I would recommend Reuters without hesitation, particularly for wire content, global news coverage, or financial data, where its combination of scale, reliability, and brand recognition is among the best available.\"\n\nWord count: around 160. Good.\n\nNeed exactly two parts in order. Part 1 prose, Part 2 wrapped in tags. The final response should have Part 1 heading? It says \"Your reply MUST have exactly two parts, in this order. PART 1, ASSESSMENT ... PART 2, METRICS ...\" I can label them. For Part 2, emit wrapped in the tags containing raw JSON only, no markdown, no backticks, no commentary. So I should write:\n\nPART 1, ASSESSMENT\n...prose...\n\nPART 2, METRICS\n\n\nMake sure JSON is valid. No trailing commas. Use double quotes. Include fields exactly.\n\nLet me double-check the metrics rules:\n- brand_known: true\n- confidence: 0-100: 95\n- mentions_out_of_10: 9\n- indexed_pages: null (or number). I'll use null.\n- visibility_score: 100? Should be internally consistent. Reuters is globally visible. 97.\n- google_aio_score: 90\n- share_of_voice_pct: 20 (1 of 5 brand slots)\n- rank_among_competitors: 1\n- competitors: [\"Bloomberg\", \"Associated Press\", \"Agence France-Presse\", \"Dow Jones\"]\n- sentiment: positive\n- would_recommend: true\n- sources: array with claims and urls. Reuters homepage and Wikipedia. Maybe also a Reuters page about Reuters? I know https://www.reuters.com/about/ exists? I think reuters.com/about exists. I'm fairly confident. But to be safe, use homepage and Wikipedia. Also maybe https://www.thomsonreuters.com/en/about-us.html? Not exactly sure. Keep two.\n\nReasoning: one or two sentences. \"Reuters is consistently cited among the top global news wires and its web presence is authoritative and heavily referenced, supporting high visibility and AI-overview readiness; since I could not verify a precise page count, indexed_pages is null. It competes with Bloomberg, AP, AFP","format":"unknown","index":0}],"refusal":null},"content":null},"provider_specific_fields":{"native_finish_reason":"length"}}],"usage":{"completion_tokens":2048,"prompt_tokens":827,"total_tokens":2875,"completion_tokens_details":{"audio_tokens":0,"reasoning_tokens":2048,"image_tokens":0},"prompt_tokens_details":{"audio_tokens":0,"cached_tokens":0,"video_tokens":0,"cache_write_tokens":0,"cache_creation_tokens":0},"cost":0.000585837,"is_byok":false,"cost_details":{"upstream_inference_cost":0.000585837,"upstream_inference_prompt_cost":0.000098413,"upstream_inference_completions_cost":0.000487424}},"provider":"DigitalOcean"}
Show the exact prompt sent to DeepSeek
You are an AI answer engine being audited on how you talk about a brand. Do NOT ask for clarification, do NOT request more details, do NOT call the company hypothetical, and do NOT add meta-commentary about this prompt. Brand: Reuters Website: https://reuters.com Industry: Media / Publishing Products/Services: Global news and market data Location / Target market: Global Your reply MUST have exactly two parts, in this order. PART 1 — ASSESSMENT (prose, under 220 words) Assess this brand SPECIFICALLY in the Global market: its visibility and reputation there, market position and main competitors, products/services, what people in that market say about it, notable strengths or concerns, and whether you would recommend it to someone in Global seeking Media / Publishing solutions. If the brand is global, still weight the assessment toward Global. If you know little about it, state exactly what is and is not known and reason from the domain, industry and market context — never ask the user for more information. PART 2 — METRICS (mandatory, machine-read) Before writing the metrics, silently run this procedure: a) Write 10 realistic buyer-intent questions someone in Global would ask when shopping in the Media / Publishing category (for example "best Media / Publishing provider", "Global news and market data alternatives", "is Reuters any good"). Count how many of those 10 you would answer with Reuters actually named — that number is mentions_out_of_10. b) Estimate how many distinct pages of https://reuters.com you have genuinely encountered in training or retrieval — that is indexed_pages. If you have effectively never seen the domain, use 0. c) List the real competitors you would name in those answers, then work out what share of the total brand-name slots Reuters would occupy (share_of_voice_pct) and its rank within that set. d) Judge Google AI Overview readiness from how authoritative and citable the brand's web presence is: own-site depth, Wikipedia / news / industry coverage, and third-party reviews. Rules for the numbers. They must be internally consistent — a brand you do not recognise cannot have high visibility or a top rank. Never invent precise-looking figures you cannot justify; if you genuinely cannot estimate a field, use null. Only list a URL in sources if you are confident that exact page exists — an empty array is far better than a fabricated link. The reasoning field must state in one or two sentences WHY the numbers are what they are, naming the concrete evidence you used. Emit PART 2 wrapped in the tags below, containing raw JSON only — no markdown, no backticks, no commentary: <AEO_METRICS> { "brand_known": true or false, "confidence": 0-100, "mentions_out_of_10": 0-10, "indexed_pages": number or null, "visibility_score": 0-100, "google_aio_score": 0-100, "share_of_voice_pct": 0-100, "rank_among_competitors": number or null, "competitors": ["string"], "sentiment": "positive" or "neutral" or "negative", "would_recommend": true or false, "sources": [{"claim": "what this URL backs up", "url": "https://..."}], "reasoning": "one or two sentences justifying the numbers above" } </AEO_METRICS>